
RLHF stands for Reinforcement Learning from Human Feedback. What role does it play in training Claude?
Select an answer to reveal the explanation.
Short Explanation
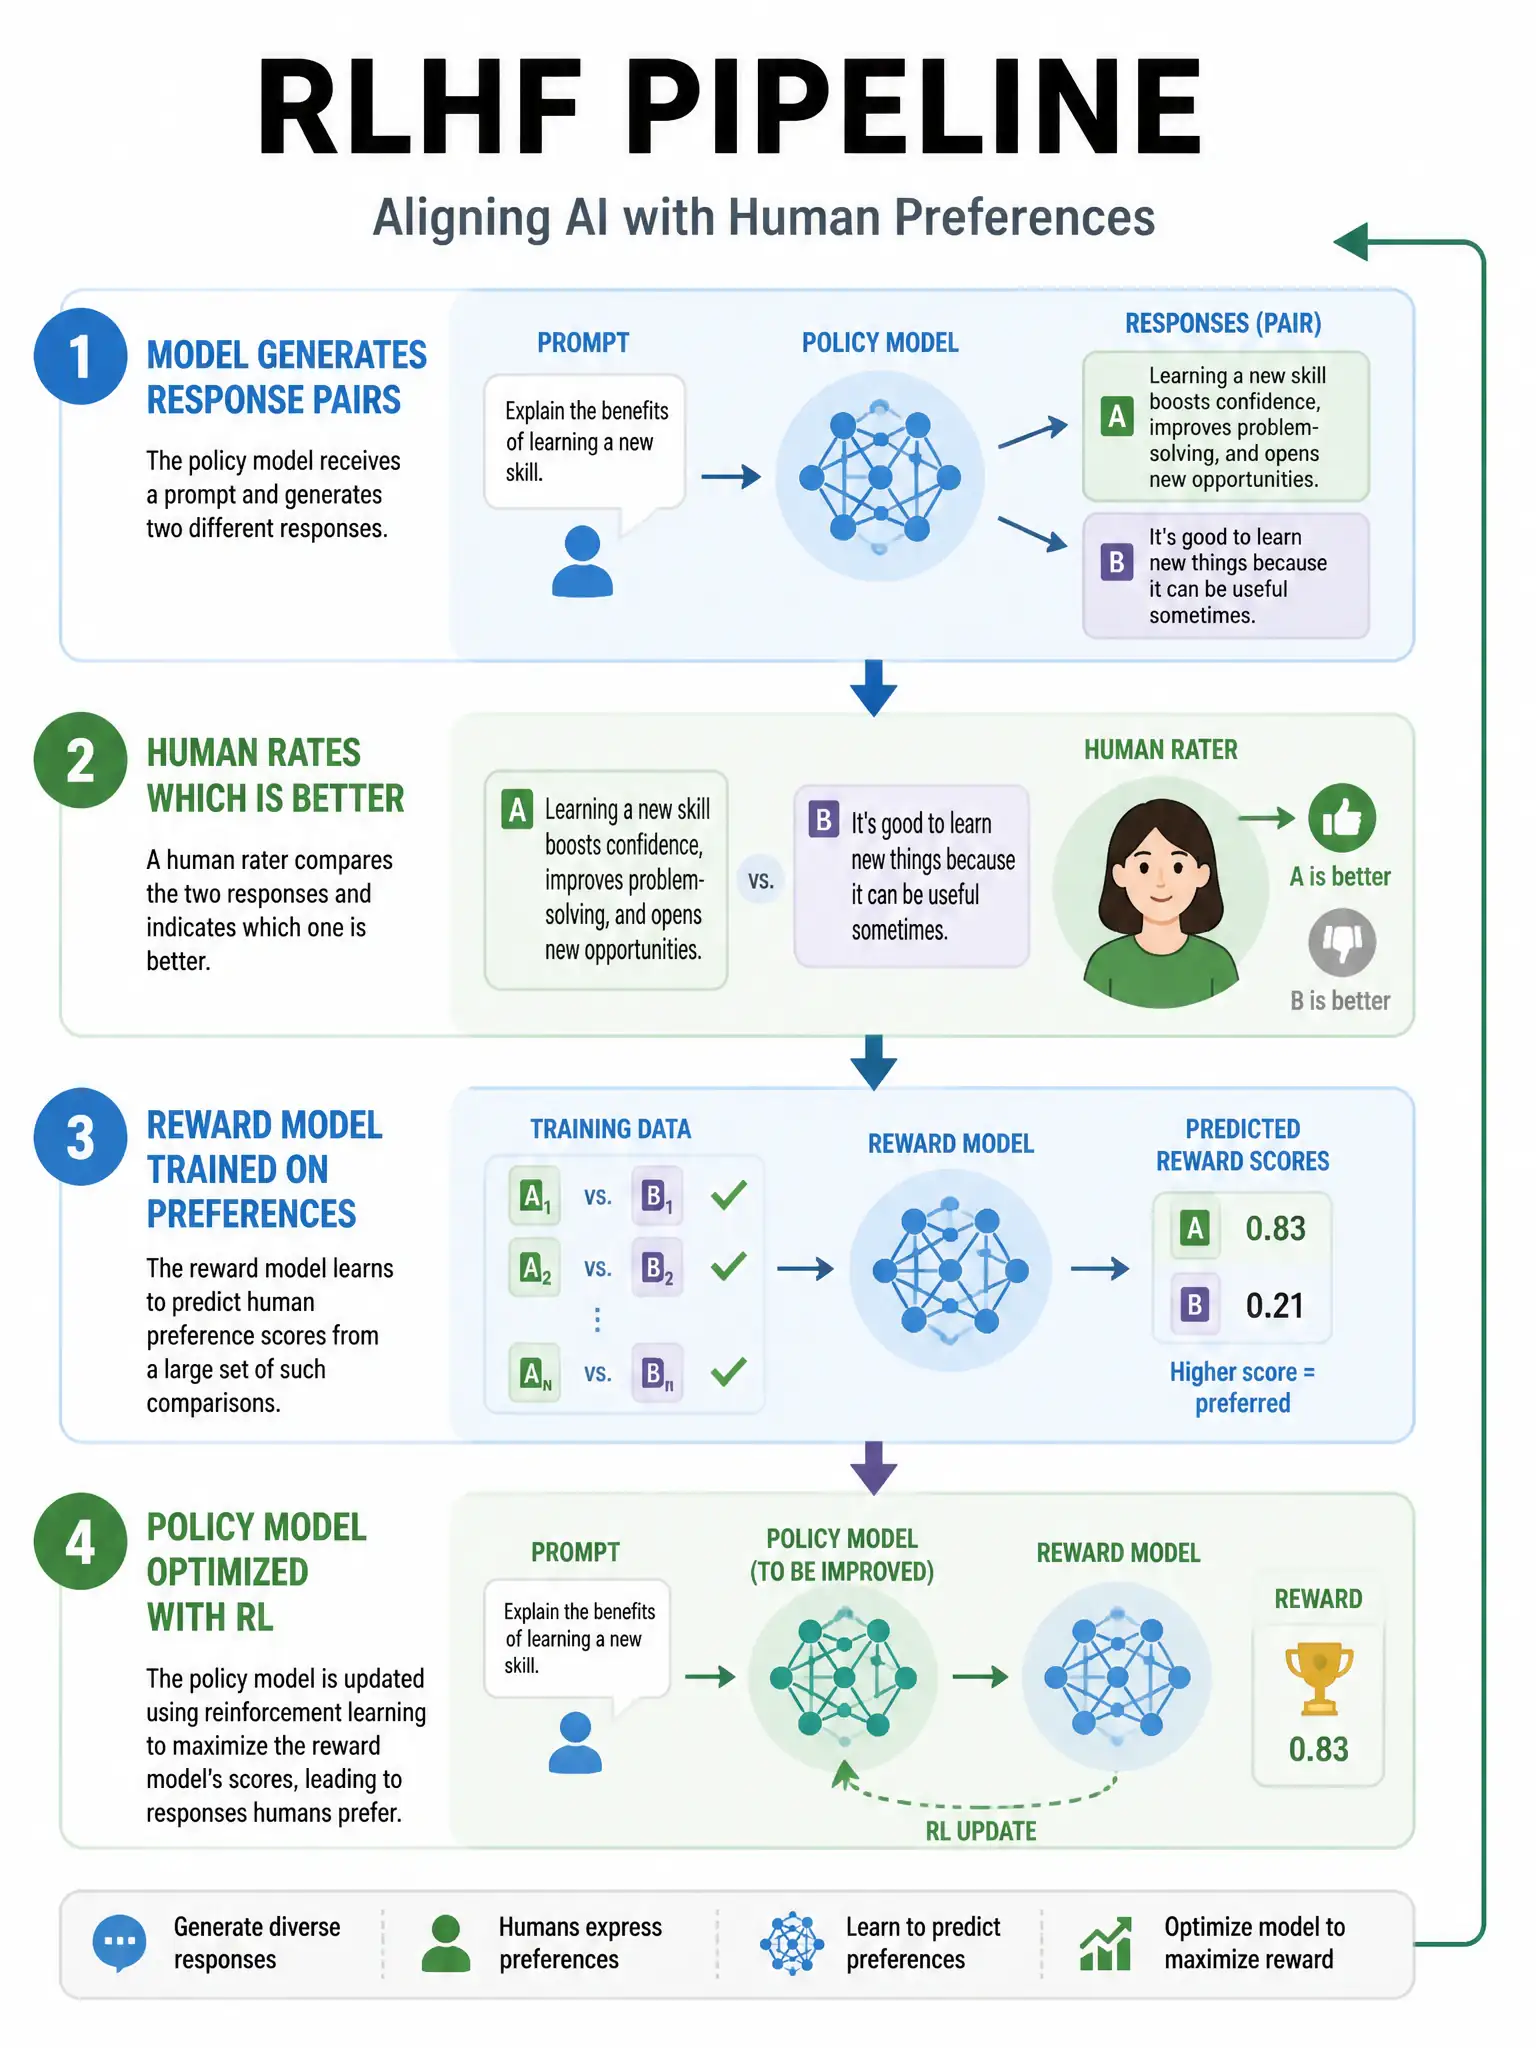
RLHF is like having expert editors rate thousands of the model's drafts. You learn which style of writing gets the thumbs up, so the model gets fine-tuned toward more helpful and safe responses.
Full Explanation
RLHF involves training a reward model based on human preference judgments, then using reinforcement learning to optimize the language model toward outputs that score highly on that reward model. Human annotators compare pairs of model responses and indicate which is better, such as more helpful, safer, or more honest. This feedback signal shapes Claude toward preferred behavior. The idea that humans compete against the model in games misunderstands the process entirely. The idea that Claude autonomously browses the internet and learns from human-written content in real time describes real-time learning, which Claude does not do; it learns during training, not inference. The idea that it is a technique exclusive to robotics that teaches physical movement patterns is completely unrelated to language models.